Machine learning operations (MLOps) tools automate and standardize how teams build, deploy, and monitor machine learning (ML) models in production. They apply DevOps principles to problems specific to ML: evolving data, non-deterministic outputs, model drift, and the need to reproduce a result months after it first shipped.
The hard part of ML is running models reliably, securely, and at scale in production. MLOps has expanded to match. It now spans large language model operations (LLMOps), covering prompt management, evaluation, and guardrails for large language models (LLMs), along with agentic AI operations and ML-specific continuous integration and continuous delivery or deployment (CI/CD) pipelines.
A typical MLOps pipeline ingests data, uses feature engineering to identify relevant input variables, trains and validates models, deploys them into production, then applies continuous monitoring and retraining to maintain performance.
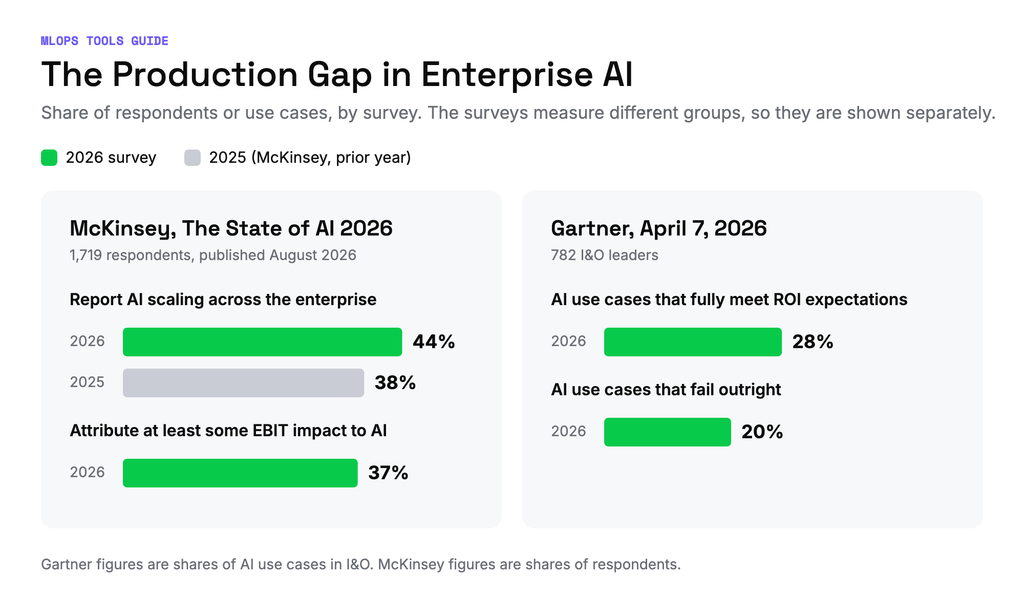
The production gap is expensive. McKinsey’s 2026 State of AI survey of 1,719 respondents, published in August 2026, found that 44% report AI scaling across their enterprise, up from 38% a year earlier, while 37% attribute at least some earnings before interest and taxes (EBIT) impact to AI, about the same share as last year. Gartner’s April 2026 survey of 782 infrastructure and operations (I&O) leaders found that 28% of AI use cases in I&O fully meet return on investment (ROI) expectations, and 20% fail outright. Moving models from experiment to dependable production is the work MLOps tools exist to do.
This guide covers the seven functional categories of a modern MLOps stack, a best-tool choice for each function (two for workflow orchestration), and a framework for choosing among them. Each top choice names where it fits and lists alternatives. Anaconda publishes this guide and is the choice for one category: environment and dependency management.
The 8 best MLOps tools at a glance
| Function | Best tool | License model | Alternatives |
|---|---|---|---|
| Environment and dependency management | Anaconda | Commercial platform built on open-source conda | Poetry, conda-forge, Docker, pip |
| Experiment tracking and model management | MLflow | Open source (Apache 2.0) | Weights & Biases, DagsHub, ClearML |
| Data versioning and management | lakeFS | Open source (Apache 2.0) with a managed cloud option | DVC, Delta Lake, Pachyderm |
| Feature stores | Feast | Open source | Tecton, Hopsworks |
| Model serving and deployment | Seldon Core | Source-available (Business Source License) | KServe, BentoML, Ray Serve |
| Model monitoring and observability | Fiddler AI | Proprietary | Evidently AI, Arize AI |
| General-purpose workflow orchestration | Apache Airflow | Open source (Apache 2.0) | Prefect, Dagster, Kedro |
| ML-native workflow orchestration | Metaflow | Open source, with enterprise capabilities through Anaconda Platform | Kubeflow, Argo Workflows |
Understanding MLOps tools
MLOps tools are easiest to understand by what they enable at each stage of the ML lifecycle. Categories overlap in practice, and a gap in any one compounds as a workflow moves toward production. A team with strong experiment tracking and no model monitoring ships models it cannot observe. Workloads have also changed: traditional ML pipelines now run alongside LLM and agentic workloads, which makes orchestration and production readiness central to MLOps.
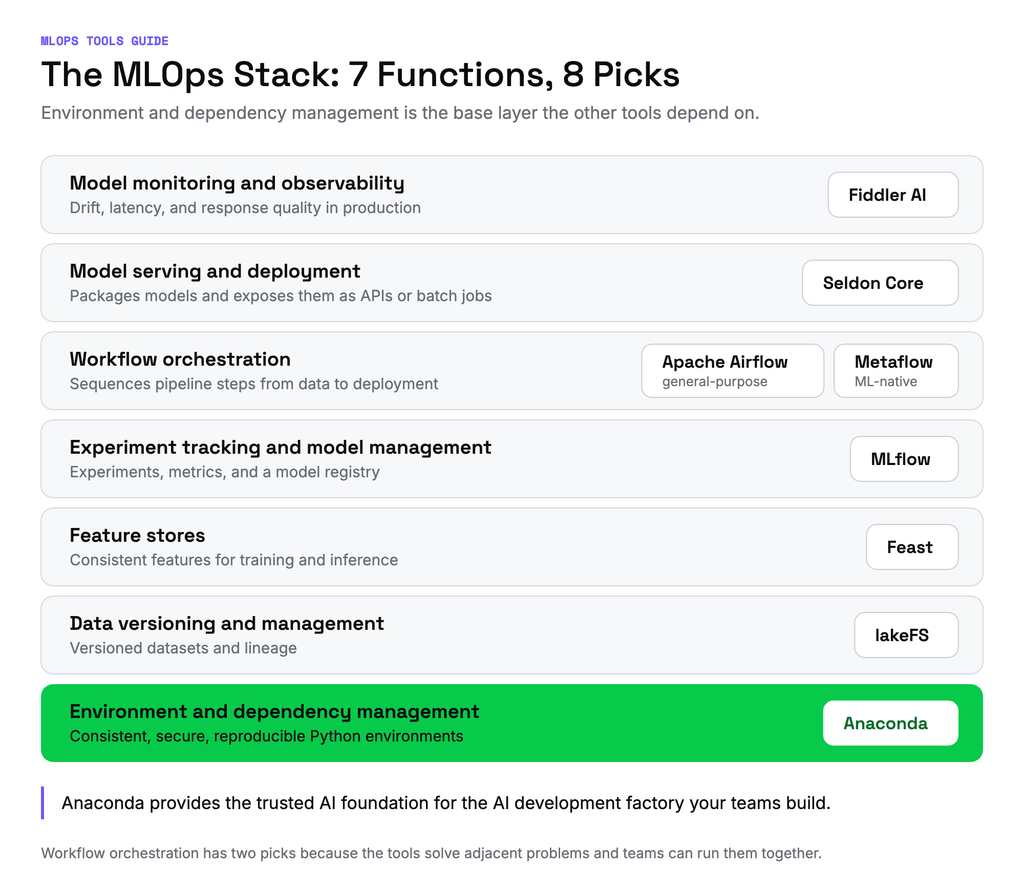
Machine learning environment and dependency management
What it does: Keeps Python environments, packages, and dependencies consistent, secure, and reproducible at each stage of the ML lifecycle, and records which package versions ran where
Why it sits at the base of the stack: Python-based experiment trackers, orchestrators, and feature stores depend on package versions resolving the same way each time. This layer addresses binary dependency conflicts, open-source supply chain risk from unvetted packages, and environment drift across laptops and deployment targets.
Without it: Models pass tests in development and fail in production because a package version resolved differently on another machine, and enterprises can lose visibility into which open-source components run inside their ML pipelines. Anaconda’s eight levels of reproducibility offer a diagnostic.
Experiment tracking and model management
What it does: Records experiments, including hyperparameters, metrics, code versions, and artifacts, and maintains a model registry that links a production model to the training parameters that produced it
Without it: Teams cannot reproduce a successful training run, explain why they chose one model over another, or provide an audit trail to a regulator. In regulated industries, that is a critical failure.
Data versioning and management
What it does: Versions datasets, tracks data lineage, and maintains data quality across ML projects, so snapshots and transformation logic stay tied to the model
Without it: Teams cannot retrain on the exact data that produced an earlier model, audit lineage when something goes wrong, or debug a production issue that traces back to an undocumented data change.
Feature stores
What it does: Acts as a centralized repository for storing, managing, and serving features so training and inference use consistent inputs. It addresses training-serving skew, which occurs when features computed during training differ from features available at inference time, so the model returns wrong outputs without raising an error.
Without it: Feature logic gets duplicated across teams, and models degrade in production for reasons that never surface in testing.
Model serving and deployment
What it does: Packages trained models for production, exposes them as scalable application programming interfaces (APIs) or batch jobs, and manages versioning across staging and production with rollback support. It also supplies the release mechanics that make AI model deployment safe: canary rollouts, blue-green cutover, and A/B testing between model versions.
Without it: Model updates require manual intervention, rollbacks are slow and risky, and no one can trace which model version produced a specific production outcome.
Model monitoring and observability
What it does: Tracks model health in production, covering data drift when input distributions change, concept drift when the relationship between inputs and outputs changes, latency, and resource use. Monitoring now also covers LLM-specific concerns, including hallucination detection, response quality evaluation, token cost tracking, and guardrail enforcement.
Without it: Model performance degrades without an alert, teams react to incidents after they occur, and compliance requirements go unmet because there is no evidence trail.
Workflow orchestration
What it does: Automates and sequences the steps of ML pipelines, from data ingestion through deployment, managing dependencies, retries, scheduling, and execution logs.
Orchestration versus CI/CD: Orchestration manages ML-specific work moving from data to features to model to evaluation. CI/CD manages software delivery moving from code to test to deploy. Mature MLOps stacks use both: continuous integration validates model performance on each pull request, continuous delivery promotes validated models from staging to production, and continuous training triggers retraining when drift thresholds or data-freshness conditions are met.
Without it: Pipelines require manual intervention at each step, failures cascade downstream, and scaling from one data scientist’s experiment to a repeatable production pipeline becomes fragile.
8 best MLOps tools by function
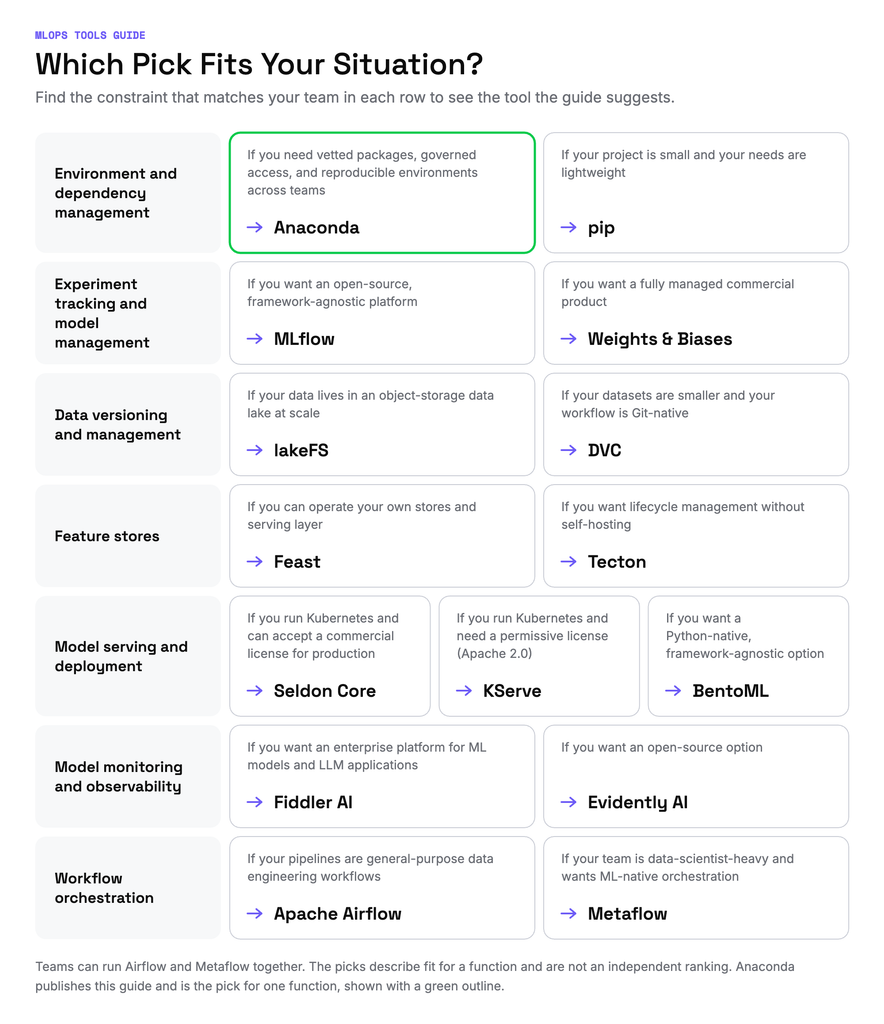
Each pick below names the tool that fits a function and a situation, the reasons teams choose it, and the alternatives worth comparing. The picks describe fit for a function and are not an independent ranking.
1. Anaconda: best for environment and dependency management
The Python-based tools in this guide depend on the environments and packages beneath them, so their reliability depends on that layer. Anaconda Platform provides a trusted AI foundation: trusted packages, reproducible environments, and governed access from local experimentation through production. You keep the tools and infrastructure you have chosen.
Why teams choose it:
- Curated packages: Anaconda Platform provides vetted, trusted open-source Python packages with vulnerability monitoring and license compliance tracking, which reduces binary dependency conflicts and supply chain risk that cause silent failures between training, staging, and production. Environments are built on conda, an open-source package and environment manager.
- Reproducible environments: Version-controlled conda environments keep configurations consistent across laptops, cloud, hybrid, and on-premises infrastructure.
- Governed access: Role-based access control sets which packages, models, and environments teams can use, and package auditing flags drift from approved configurations.
- Curated models: Teams select from vetted, governance-approved models instead of pulling unvetted model weights from unmanaged registries. Anaconda’s guidance on AI model security covers the pipeline stages where that matters.
- Orchestration for production: Anaconda Platform AI orchestration runs repeatable, traceable workflows from development to production across hybrid, multi-cloud, and on-premises infrastructure, with graphics processing unit (GPU) access, experiment tracking, artifact management, and lineage.
Standard fields:
- Open-source vs proprietary: Built on open-source conda and the Python ecosystem. Anaconda Platform adds enterprise governance, security, compliance, and support, including AI security and guardrails.
- Security measures: Package vulnerability scanning and monitoring, license compliance tracking, role-based access control, single sign-on, audit logging, and package auditing against approved configurations.
- Integrations: VS Code, Jupyter notebooks, and the integrated development environments (IDEs) your teams already use. Workloads run on Amazon Web Services (AWS), Azure, Google Cloud, and on-premises infrastructure.
- Cost and pricing models: Individual, academic, business, and enterprise plans. See Anaconda plans and pricing.
Alternatives: Poetry manages Python dependencies with lockfiles, and vulnerability scanning and enterprise governance come from separate tools. Conda-forge is a community-maintained channel of conda packages, so teams that need commercial support or centrally enforced package policies add them separately. Docker isolates at the operating system level, so dependency resolution still happens inside the container. Pip suits smaller projects.
2. MLflow: best for experiment tracking and model management
MLflow is an open-source, framework-agnostic platform for managing the ML lifecycle. It has expanded from experiment tracking into LLM and agent workflows.
Why teams choose it:
- Experiment tracking across parameters, metrics, code versions, and artifacts through a searchable interface
- A model registry for versioning, staging, and promoting models with an audit trail
- LLM capabilities, including prompt management, an evaluation function for scoring generative outputs, an AI gateway for cost and access control, and agentic trace logging
Standard fields:
- Open-source vs proprietary: Open-source under Apache 2.0, with managed options available through data platforms.
- Security measures: Authentication and authorization support, with access control and audit capabilities that depend on the hosting environment or managed offering.
- Cost and pricing models: Free and open-source; managed offerings are priced by the hosting platform.
Practical boundaries: MLflow links experimentation to production, but it does not replace workflow orchestration, data versioning, or production serving infrastructure.
Alternatives: Weights & Biases is a commercial option for teams that want a fully managed product. DagsHub combines experiment tracking with data versioning. ClearML offers an open-source suite spanning tracking, orchestration, and dataset versioning.
3. lakeFS: best for data versioning and management
lakeFS is a Git-like data version control system for data lakes, licensed under Apache 2.0, with a managed cloud option.
Why teams choose it:
- Git-like branching, committing, and merging applied to data in object storage at data lake scale, with atomic, reversible changes
- A clear path alongside data version control (DVC): in November 2025, lakeFS announced that it had acquired the DVC open-source project from Iterative.ai. DVC continues as an independent open-source tool for smaller datasets.
Standard fields:
- Open-source vs proprietary: Open-source under Apache 2.0, with a managed cloud option.
- Security measures: Security features vary by edition. See the lakeFS documentation.
- Cost and pricing models: Free open-source tier with paid managed plans.
Practical boundaries: Data versioning is a prerequisite for reproducible MLOps, because without it an audit trail through the model registry stops at the model. lakeFS is not a feature store, and it assumes an object-storage-backed data lake, which makes it a poor fit for teams whose data lives primarily in a warehouse.
Alternatives: DVC, now under lakeFS stewardship, remains a lightweight option for Git-native data version control. Delta Lake provides versioned data lake storage with transactional guarantees. Pachyderm couples data versioning with pipeline automation on Kubernetes.
4. Feast: best for feature stores
Feast is an open-source, end-to-end feature store. Gojek and Google developed it together in 2018, and it is now a Linux Foundation AI & Data (LF AI & Data) incubation project, which places it under vendor-neutral foundation governance.
Why teams choose it:
- Stores and serves features consistently across model training and inference, which directly mitigates training-serving skew
- An offline store for historical batch processing, a low-latency online store for real-time prediction, and a feature server for serving precomputed features online
Standard fields:
- Open-source vs proprietary: Open-source.
- Cost and pricing models: Free and open-source.
Practical boundaries: Feast defines and serves features but does not compute them. Transformation pipelines still live in your data engineering stack, and running Feast in production requires operating its stores and serving layer.
Alternatives: Tecton is a managed feature platform for teams that want lifecycle management without self-hosting. Hopsworks emphasizes observability and enterprise governance for regulated environments.
5. Seldon Core: best for model serving and deployment
Seldon Core is a Kubernetes-native framework for deploying models into production. Seldon Core 2 positions itself as an MLOps and LLMOps framework, extending beyond traditional model serving into LLM application deployment.
Why teams choose it:
- Kubernetes-native architecture, which suits organizations already standardized on Kubernetes
- Inference graphs that compose multiple models, transformers, and routers into a single served pipeline, which supports A/B testing and canary patterns
Standard fields:
- Open-source vs proprietary: Since January 2024, Seldon Core has been licensed under the Business Source License 1.1, which is source-available and not an open-source license. Non-production use is free, and for-profit organizations must obtain a commercial license for production use. Verify the terms for your version against your legal requirements before standardizing on it.
- Cost and pricing models: Commercial license required for production use. Contact Seldon for pricing.
Practical boundaries: Seldon Core does not handle experiment tracking, data versioning, or model monitoring. It assumes Kubernetes expertise, which is an adoption cost for teams with many data scientists, and the license makes the production path commercial.
Alternatives: Teams that want a permissively licensed serving layer should evaluate KServe, which is Kubernetes-native under Apache 2.0 and a Cloud Native Computing Foundation (CNCF) project, and BentoML, which is Python-native, framework-agnostic, and earned an “adopt” rating for inference in the Q4 2025 CNCF Technology Landscape Radar. Ray Serve fits where the same cluster handles distributed training and inference.
6. Fiddler AI: best for model monitoring and observability
Fiddler AI is an enterprise AI observability platform that covers traditional ML models and LLM applications.
Why teams choose it:
- Monitoring, analysis, and protection of models across training and production, covering data drift, concept drift, prediction quality, and performance degradation
- LLM application observability alongside traditional model monitoring, including response quality and safety evaluation, so teams do not need a separate tool for each workload type
- Explainability tooling that supports root-cause analysis when a model’s behavior changes
Standard fields:
- Open-source vs proprietary: Proprietary platform.
- Security measures: SOC 2 Type II compliance, audited annually, and Health Insurance Portability and Accountability Act (HIPAA) compliance, according to Fiddler’s security page.
- Cost and pricing models: Plans range from free to custom enterprise pricing, with a usage-based developer tier. See Fiddler pricing.
Practical boundaries: Monitoring is the feedback loop in an MLOps pipeline, because without it teams cannot trigger retraining or rollback on evidence. Fiddler does not handle training, deployment, or orchestration, and as a proprietary platform, its costs scale with usage.
Alternatives: Evidently AI is an open-source option covering data drift, prediction drift, and model quality monitoring, with LLM evaluation support. Arize AI is a commercial option that adds embedding drift and LLM monitoring.
7. Apache Airflow: best for general-purpose workflow orchestration
Workflow orchestration gets two picks because the tools solve adjacent problems and teams can run them together. Apache Airflow is an open-source, general-purpose, code-centric workflow management platform for data engineering pipelines.
Why teams choose it:
- Airflow 3.0, released in April 2025, shipped a rewritten React-based interface, native directed acyclic graph (DAG) versioning that preserves the exact code and structure a historical run executed under, and event-driven scheduling that triggers workflows from external events as well as from cron.
- At release, the Airflow project reported more than 30 million monthly downloads and 80,000 organizations, with over 30% of users running it for MLOps.
- In the Q4 2025 CNCF Technology Landscape Radar, Airflow topped usefulness and recommendation ratings in ML orchestration and reached “adopt” status.
Standard fields:
- Open-source vs proprietary: Open-source under the Apache Software Foundation.
- Cost and pricing models: Free and open-source; managed offerings are available from multiple vendors.
Practical boundaries: Airflow is an orchestration backbone for production MLOps pipelines, but it is not purpose-built for ML. It lacks native experiment tracking and feature management, and DAG complexity can grow quickly as pipelines expand.
Alternatives: Prefect offers Python-native orchestration with dynamic workflows and built-in retry and error handling. Dagster provides data-aware, asset-based orchestration. Kedro suits teams that want opinionated pipeline structure and project conventions instead of a scheduler.
8. Metaflow: best for ML-native workflow orchestration
Metaflow is a Python-first, ML-native orchestration framework. Created at Netflix for production ML and AI workflows and released as open source, it scales from local experimentation to cloud production and underpins Anaconda Platform AI orchestration.
Why teams choose it:
- It suits data-scientist-heavy teams that find Kubernetes-native orchestrators complex to adopt directly.
- In the Q4 2025 CNCF Technology Landscape Radar, Metaflow led ML orchestration on maturity, with 84% of respondents giving it four or five stars, and earned an “adopt” rating. Kubeflow and Argo Workflows were rated “trial.”
- Anaconda’s technical overview of why ML and AI developers choose Metaflow covers its design philosophy in more depth.
Standard fields:
- Open-source vs proprietary: Open-source, with enterprise capabilities available through Anaconda Platform AI orchestration.
- Security measures: Runs inside your own cloud account or on-premises infrastructure, so data and compute stay within existing security boundaries.
- Integrations: AWS, Azure, Google Cloud, on-premises and GPU infrastructure, Kubernetes, and a Metaflow-Kubeflow integration for deploying as Kubeflow Pipelines on existing clusters.
- Cost and pricing models: Free and open-source; enterprise pricing through Anaconda Platform.
Practical boundaries: Metaflow closes the gap between the experiment a data scientist runs locally and the pipeline that runs in production. It is ML-focused, so it is not the right choice for orchestrating a broad enterprise data platform, and teams that run large Airflow estates can add it for ML workflows without replacing Airflow.
Alternatives: Kubeflow and Argo Workflows are Kubernetes-native options, rated “trial” for orchestration in the CNCF radar, for teams that can absorb the added operational complexity.
MLOps tools vs platforms
The choice between individual tools and a unified platform emerges as ML work matures and the cost of stitching tools together becomes visible. Individual tools let experienced data scientists customize a pipeline, and that flexibility has a cost curve. Environments drift across team members and deployment targets. Experiment metadata, model artifacts, and deployment logs live in separate systems with no unified view. Open-source dependencies introduce security and licensing risk that nobody manages. The integration work becomes custom glue code with its own maintenance burden.
MLOps and AI platforms address this without eliminating the specialized tools in this guide. They provide a standardized core workflow with tool plug-ins, a unified audit trail and shared model registry, centralized governance, and orchestration that spans experimentation to production. Common platform options include:
- Databricks offers a unified lakehouse with native MLflow, model serving, a feature store, and monitoring.
- Amazon SageMaker AI provides an end-to-end managed environment on AWS.
- Azure Machine Learning is Azure-native, with Prompt Flow for LLM pipelines.
- Google’s Gemini Enterprise Agent Platform, formerly Vertex AI, is Google Cloud-native and integrates with Google’s Agent Development Kit.
- Kubeflow is a Kubernetes-native, open-source platform for Kubernetes-centric infrastructure.
Anaconda does not ask you to replace any of these. It works across the models, packages, developer tools, clouds, and infrastructure you have already chosen and provides a trusted AI foundation beneath them: trusted packages, reproducible environments, and repeatable workflows from local experimentation to hybrid and on-premises production, without forcing migration or a new execution model. Cloud platforms provide AI services within their own ecosystems, and Anaconda helps you keep consistent trust, governance, and choice across models, tools, clouds, and vendors.
How to choose the right MLOps tool
When you choose an MLOps tool, fit with your organization’s actual conditions matters more than feature count. Weigh these factors:
- Ease of use: Assess whether the people who use the tool will adopt it in practice. Tools that require data scientists to leave Jupyter notebooks or their existing IDE face resistance that a feature list will not offset.
- Interoperability: Evaluate how the tool fits your existing infrastructure and data sources, and whether integrations exist for the libraries and platforms you already run. Trace how data moves from storage through feature engineering, training, deployment, monitoring, and retraining. Failures to watch for include manual handoffs such as copy-pasting a model path and monitoring that cannot trace an alert back to the model version and training data that produced it.
- Scalability: Separate scalability into three dimensions: data and model volume, number of team members, and pipeline complexity. A tool that scales training may not scale governance.
- Community: Look for an active community. Neutral foundation governance, as with Airflow and Feast, reduces the risk that a project’s direction shifts with a single vendor’s commercial strategy.
- Open source: Treat this as a spectrum. Open-source tools offer transparency, flexibility, and freedom from vendor lock-in. At enterprise scale, that same openness can create fragmented tool use across teams, limited visibility into which versions are deployed where, unmanaged security and licensing exposure, and shadow AI, meaning teams running unapproved models and tools outside any governance process. Anaconda helps you govern open-source usage while keeping its speed and flexibility. AI governance closes those gaps.
- Budget and total cost of ownership: Cost extends well past licensing. Include infrastructure, support, and integration time. Open-source tools are free to adopt but carry operational overhead at scale, and managed platforms introduce usage-based costs that climb with model count, data volume, and team size. Also price the exit, because migration cost determines whether a decision is reversible.
- Production readiness and orchestration: Give this factor heavy weight. Ask whether the tool or stack can move models from experimentation into production reliably, with lineage, artifact tracking, and observability intact. A tool that improves experimentation while leaving the production path unchanged does not address the gap McKinsey and Gartner describe. Decide on deployment topology early: cloud, self-hosted, on-premises, or hybrid.
One practical recommendation for anyone approving this spending: require a baseline before purchase. Mean time from validated model to production endpoint, production incidents traced to environment or dependency issues per quarter, and percentage of production models with complete data lineage are all measurable before and after. A baseline also keeps expectations realistic. Gartner found that 57% of I&O leaders who reported at least one failure said their AI initiatives failed because they expected too much, too fast.
How Anaconda strengthens your MLOps stack
As MLOps matures, the bottleneck shifts to the layer beneath the tools in this guide. Environment consistency, dependency security, and governance determine whether your stack can scale on your terms.
Anaconda provides the trusted AI foundation for the AI development factory you are already building: the repeatable system your teams use to build, secure, govern, deploy, and operate AI. You keep the models, tools, and infrastructure you have chosen. Anaconda Platform adds four capabilities to them:
- Build with AI workspaces: Give data scientists trusted packages, models, and reproducible environments in the tools they already use, including VS Code and Jupyter notebooks.
- Secure with AI security and guardrails: Govern packages and models before they ship, with vulnerability monitoring, access policies, and audit logging that follow the workload. Learn more about Anaconda’s secure by default approach.
- Operate with AI orchestration: Run repeatable, traceable workflows from development to production across hybrid, multi-cloud, on-premises, and GPU infrastructure, with lineage and artifact tracking for experiments, models, and results.
- Trust with AI artifacts: Give teams vetted Python packages and curated models with provenance, vulnerability tracking, and license policies.
None of this replaces the tools in this guide. MLflow, lakeFS, Feast, Seldon Core, Fiddler AI, Airflow, and Metaflow work with the environments and packages Anaconda governs. A result you cannot reproduce is a result you cannot trust or ship, whether a person wrote the code or an agent did.
Build and scale an AI dev factory you can trust. Request a demo to see how Anaconda fits into your MLOps stack, or get started free to try it directly.
FAQs
What’s the difference between MLOps and AI orchestration?
MLOps is the broader discipline: the practices and tooling that get ML models into production reliably and keep them there, spanning experiment tracking, data versioning, serving, and monitoring. AI orchestration is one function within it: the layer that executes and sequences workflows, manages compute, tracks artifacts, and provides observability as work moves from experimentation to production. Anaconda Platform AI orchestration covers that layer across hybrid, multi-cloud, and on-premises infrastructure.
How do MLOps tools support LLM and generative AI workflows?
Large language models introduce operational requirements that traditional MLOps frameworks weren’t built for, and MLflow, Fiddler AI, and Seldon Core have expanded to address them. Prompt versioning treats prompts as versioned artifacts alongside model weights. Evaluation relies on automated LLM-as-a-judge pipelines that score response quality, faithfulness, and safety inside CI/CD pipelines, using suites such as Promptfoo and DeepEval. Retrieval-augmented generation pipelines need version control over vector indices and lineage for retrieved chunks, which brings vector databases such as Qdrant and application frameworks such as LangChain into the governance conversation. Cost and token monitoring track usage by model, endpoint, and workflow, while guardrail enforcement adds output filtering at the serving layer. Anaconda’s guidance on moving from MLOps to LLMOps covers the practices in more depth.
Can open-source MLOps tools handle production workloads?
Yes, with operational caveats. At its April 2025 3.0 release, the Airflow project reported more than 80,000 organizations using it, and Airflow and Metaflow each reached “adopt” status in the Q4 2025 CNCF Technology Landscape Radar. Self-hosted open-source tools require you to own infrastructure, upgrades, security patching, and access control, which adds engineering time to the business case. Licensing also needs a check, because Seldon Core moved to the source-available Business Source License in January 2024. Pairing open-source tools for the core workflow with enterprise governance for consistency, security, and compliance works at enterprise scale.
How much do MLOps tools cost?
Open-source tools like MLflow, Feast, Airflow, and Metaflow are free to adopt, but a self-hosted deployment carries infrastructure, upgrade, patching, and administration costs that grow with usage. Commercial tools vary: Fiddler AI offers plans from free to custom enterprise pricing, Seldon Core requires a commercial license for production use, except at non-profit educational institutions, and consumption-priced managed platforms cost more as model count, data volume, and team size grow. A defensible total cost of ownership model also includes integration engineering, migration and exit cost, and the cost of irreproducible results, which is spread across teams and appears in no single budget line.
How do you move ML models from experimentation to production reliably?
Reliability comes from four consistent layers. The environment layer keeps package versions consistent between training and serving, using Anaconda environments or containerized builds. The data layer locks the datasets and features that produced a given model, using data version control and a feature store. The orchestration layer runs pipelines consistently across environments, with lineage and artifact tracking intact. The CI/CD layer validates model performance on each change, promotes validated models, and triggers continuous training when drift thresholds are crossed.